BerkayKöklü

AI Engineer / ML Engineer

Building production LLM systems at Bizzbee; M.Sc. research on generative world models and offline RL at Boğaziçi University.

  • Retrieval
  • Agents
  • Evaluation
  • Reinforcement Learning
PyTorchReinforcement learning (PPO)Generative modelsLoRADiffusionTransformersAgentic RAGGraph RAGHybrid retrievalQuery routingModel routingLLM evaluationLangChainHugging FacePythonFastAPIDockerMongoDBRedisSQLGitHub Actions (CI/CD)pandasNumPy

Experience

  1. Jan 2025 - now

    AI Engineer

    Bizzbee

    Production LLM systems for a multi-tenant AI customer service platform: retrieval, generation, safety and the evaluation loops around them.

  2. Feb 2024 - Jan 2025

    Startech Intern, Intertech

    SQL Server administration: clusters, monitoring, upgrades, archiving.

  3. Jun - Oct 2023

    Software Support Intern, Sendeo

    Diagnosed production database issues across SQL, Kibana and Azure.

  4. Jan 2022 - Jul 2023

    Coding Trainer, Logiscool

    Taught block-based programming and Python across age groups.

Production work

Systems running for real users at Bizzbee: query routing, hybrid and graph retrieval, guardrails, and the evaluation around them. Diagrams first; the method is one click away.

Agentic RAG and routing

A retriever that decides how to retrieve

Built retrieval as an agent rather than a fixed pipeline: it decides whether to retrieve at all, which strategy fits the question, and whether what came back is enough to answer with.

PythonAgentic RAGQuery routingSelf-reflectionLangChainVector searchBM25
Graph RAG

Questions whose answer is spread across documents

Extracted entities and relations from the corpus into a graph, so questions that need several facts connected can be answered by traversal rather than similarity.

PythonGraph RAGEntity extractionRelation extractionMulti-hop retrieval

Three facts in three documents, found by walking the graph

Evaluation

Evaluation pipelines and feedback loops

Built evaluation pipelines and feedback loops that quantify model behaviour in production, so each iteration is judged rather than guessed.

PythonLLM evaluationFeedback loops

Every change is judged against the set before it ships. Representative example, not a production metric.

No performance figures appear on these three. The work is under NDA-shaped constraints and nothing was measured into a number I can publish and stand behind. The measured results are in the open-source work below, where anyone can reproduce them.

Open source

From LLM systems to ML experiments to generative models. Built outside work, deployed, and measured; each publishes what it found, including where the result went against me.

LLM systems

llm-cost-autopilot

An OpenAI-compatible proxy that answers with a cheap model and escalates to a reasoning model only when five of its answers disagree, trading a little accuracy for a large cost saving.

  • Model cascade
  • Escalation
  • Evaluation
  • Cost / quality trade-off
  • OpenAI-compatible API

−36%cost, at 67.3% vs 70.0% accuracy

Open the project

LLM systems

sql-agent

A text-to-SQL agent that reads tables and checks real values before it writes a query, on SQLite or PostgreSQL.

  • Tool-calling agent
  • Text-to-SQL
  • SQLAlchemy
  • PostgreSQL
  • Held-out evaluation

65.0%on 300 unseen BIRD questions, vs 57.7% one-shot

Open the project

How many accounts who choose issuance after transaction are staying in East Bohemia region?

13in 7.65 s

ML / RL

match3-rl

A match-3 environment, a PPO agent trained on it, and an evaluation across forty levels: level difficulty depends on who is playing.

  • Gymnasium
  • PPO
  • MLP policy
  • Action masking
  • Reward design
  • Stable-Baselines3

14% vs 78%careless vs careful player clearing level 27

Open the project

Greedy, level 20

42 tiles in 21 moves

cleared
0 / 42 tiles21 moves left

Generative AI

style-lora

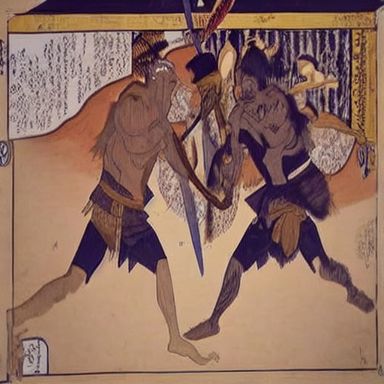
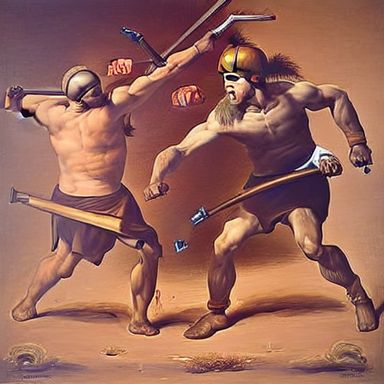
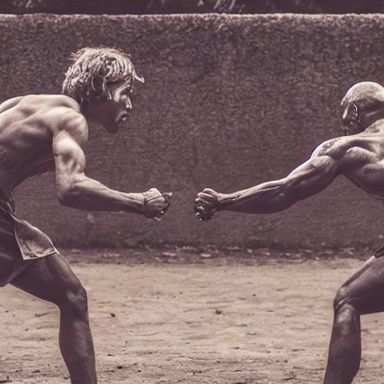
Fine-tuned Stable Diffusion with LoRA to learn two artistic styles, and evaluated the outputs with a blind comparison.

  • LoRA
  • Stable Diffusion
  • Style fine-tuning
  • CLIP
  • Blind evaluation
Open the project
“two warriors facing each other”, base model
“two warriors facing each other”, ukiyo-e adapter
“two warriors facing each other”, baroque adapter

Research interests

The directions behind my M.Sc. thesis, and how they connect. This is where I am heading, not finished work: there are no results here yet.

A learned simulator to plan inside.

If the simulator is good enough, planning no longer needs the real environment.

A world model that generates plausible trajectories lets a policy be trained and tested without acting in the real environment. That matters most exactly where acting to learn is expensive or unsafe. The part I care about is constraint: a generated trajectory is only useful if it could actually have happened.

ts-worldmodel-lab benchmarking harness

Skills

What I have actually used, grouped by what it is for.

AI / ML

  • PyTorch
  • Reinforcement learning (PPO)
  • Generative models
  • LoRA
  • Diffusion
  • Transformers

LLM systems

  • Agentic RAG
  • Graph RAG
  • Hybrid retrieval
  • Query routing
  • Model routing
  • LLM evaluation
  • LangChain
  • Hugging Face

Engineering

  • Python
  • FastAPI
  • Docker
  • MongoDB
  • Redis
  • SQL
  • GitHub Actions (CI/CD)
  • pandas
  • NumPy

Building an AI team?

Open to AI engineering, ML engineering and data science roles.